The lottery.
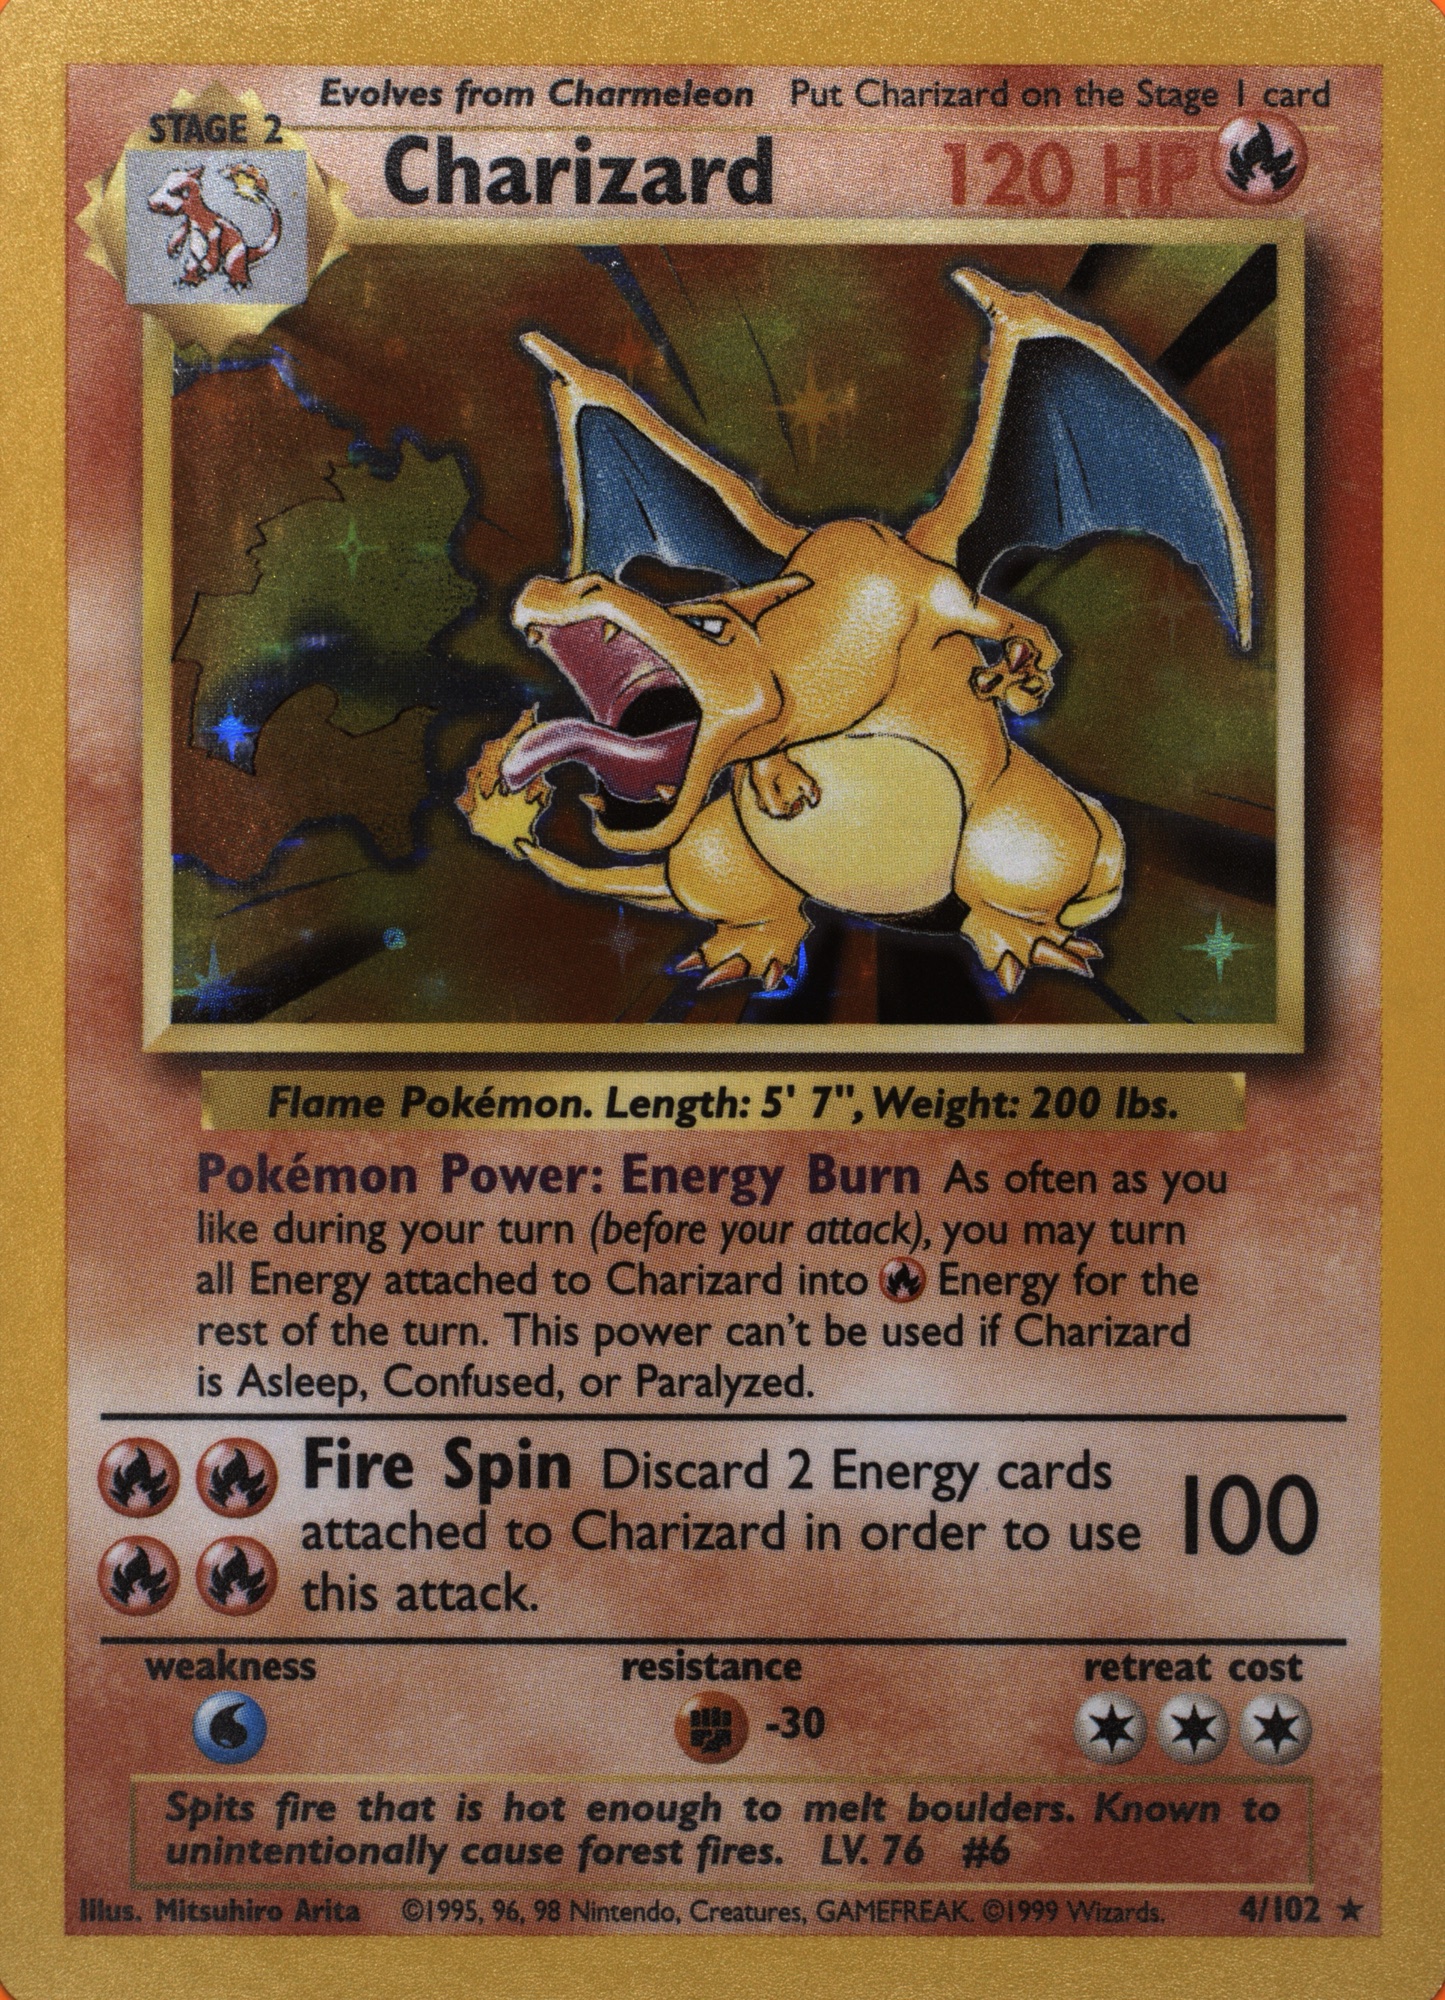
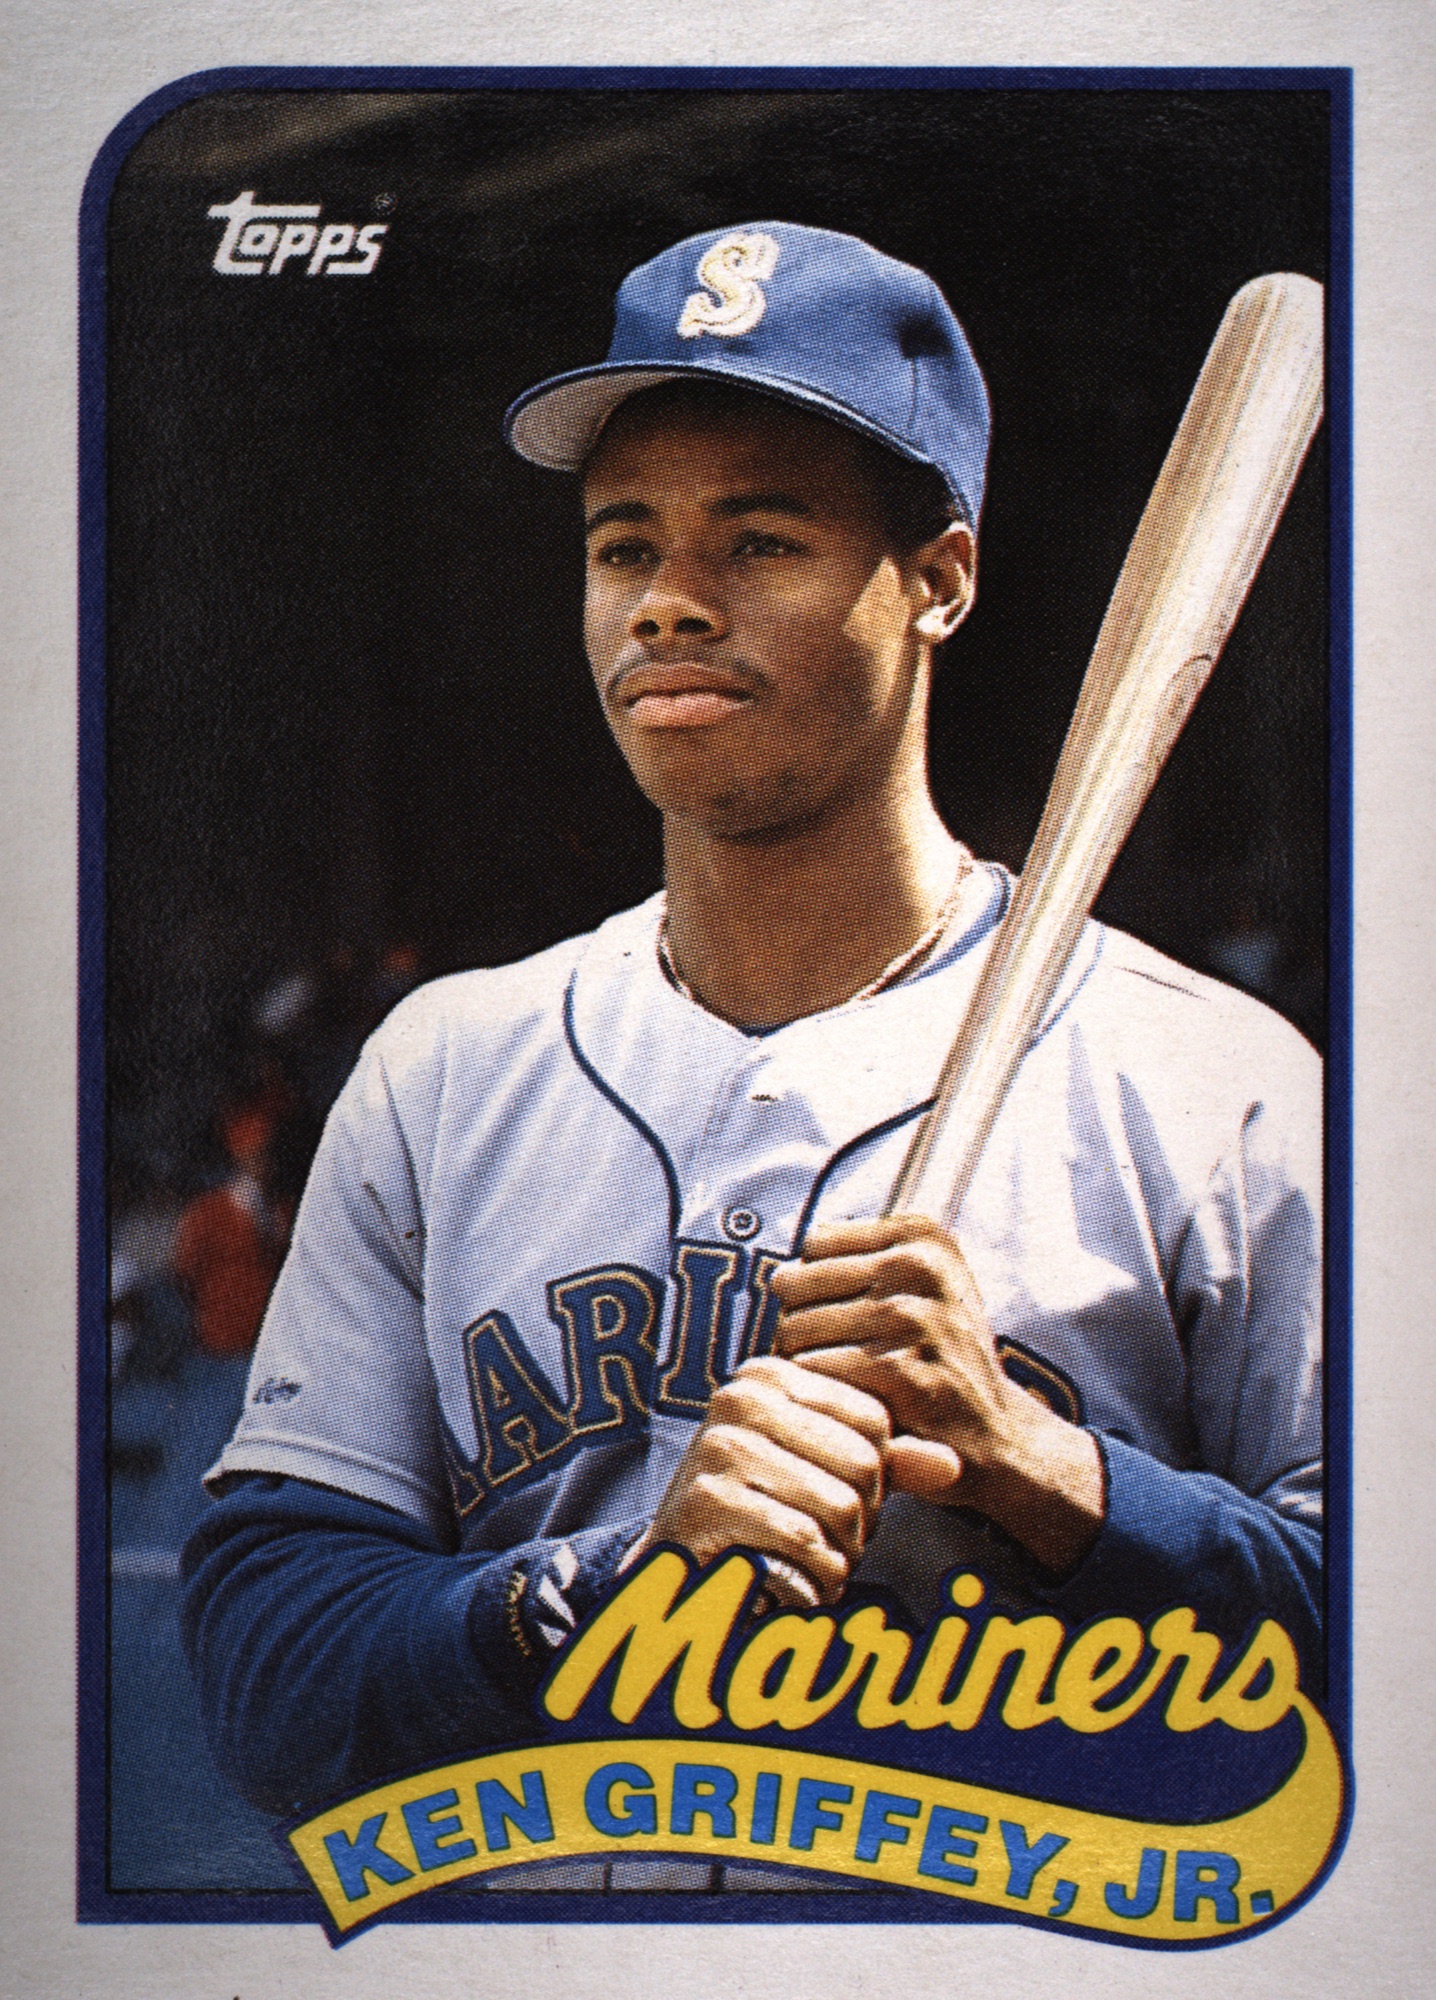
AI-powered grading
The future
of grading.
A frontier computer vision and machine learning team from CMU, applying hierarchical learning models to card grading.
Scroll
Cardinal
A hierarchical computer vision deep learning model, developed by the leaders in the field at Carnegie Mellon University.
Live inspection · FRONT · 0%
We measure the card with pixel-perfect precision: centering, edges and corners. Each measurement becomes a numeric score, backed by annotations on the image.
A low-resolution pass flags areas that need a closer look.
A high-resolution pass identifies and classifies imperfections, with annotated images for review.
Defects and measurements combine into consistent subgrades and a numeric grade.
Or use it to support a human grader: the same annotated evidence gives them what they need to make a consistent decision.
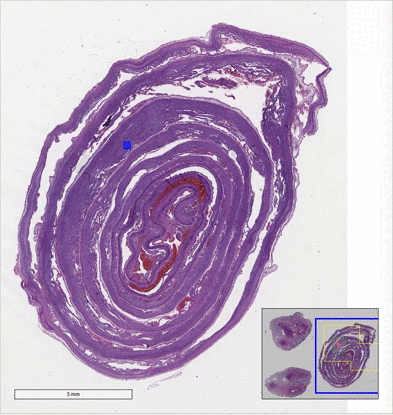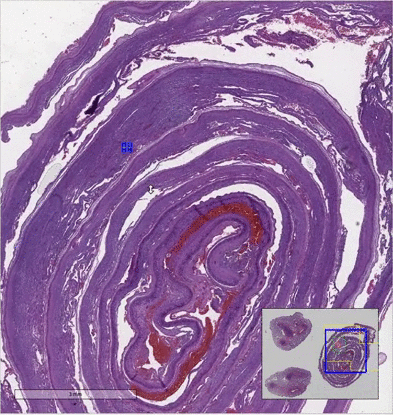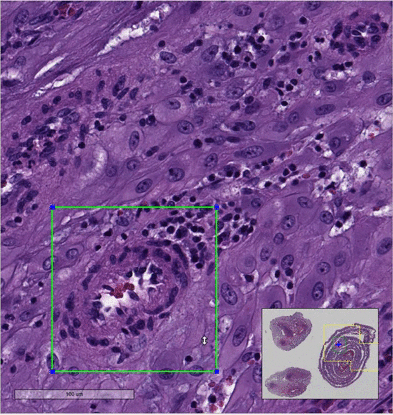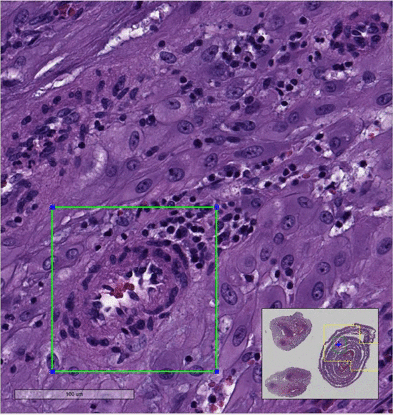
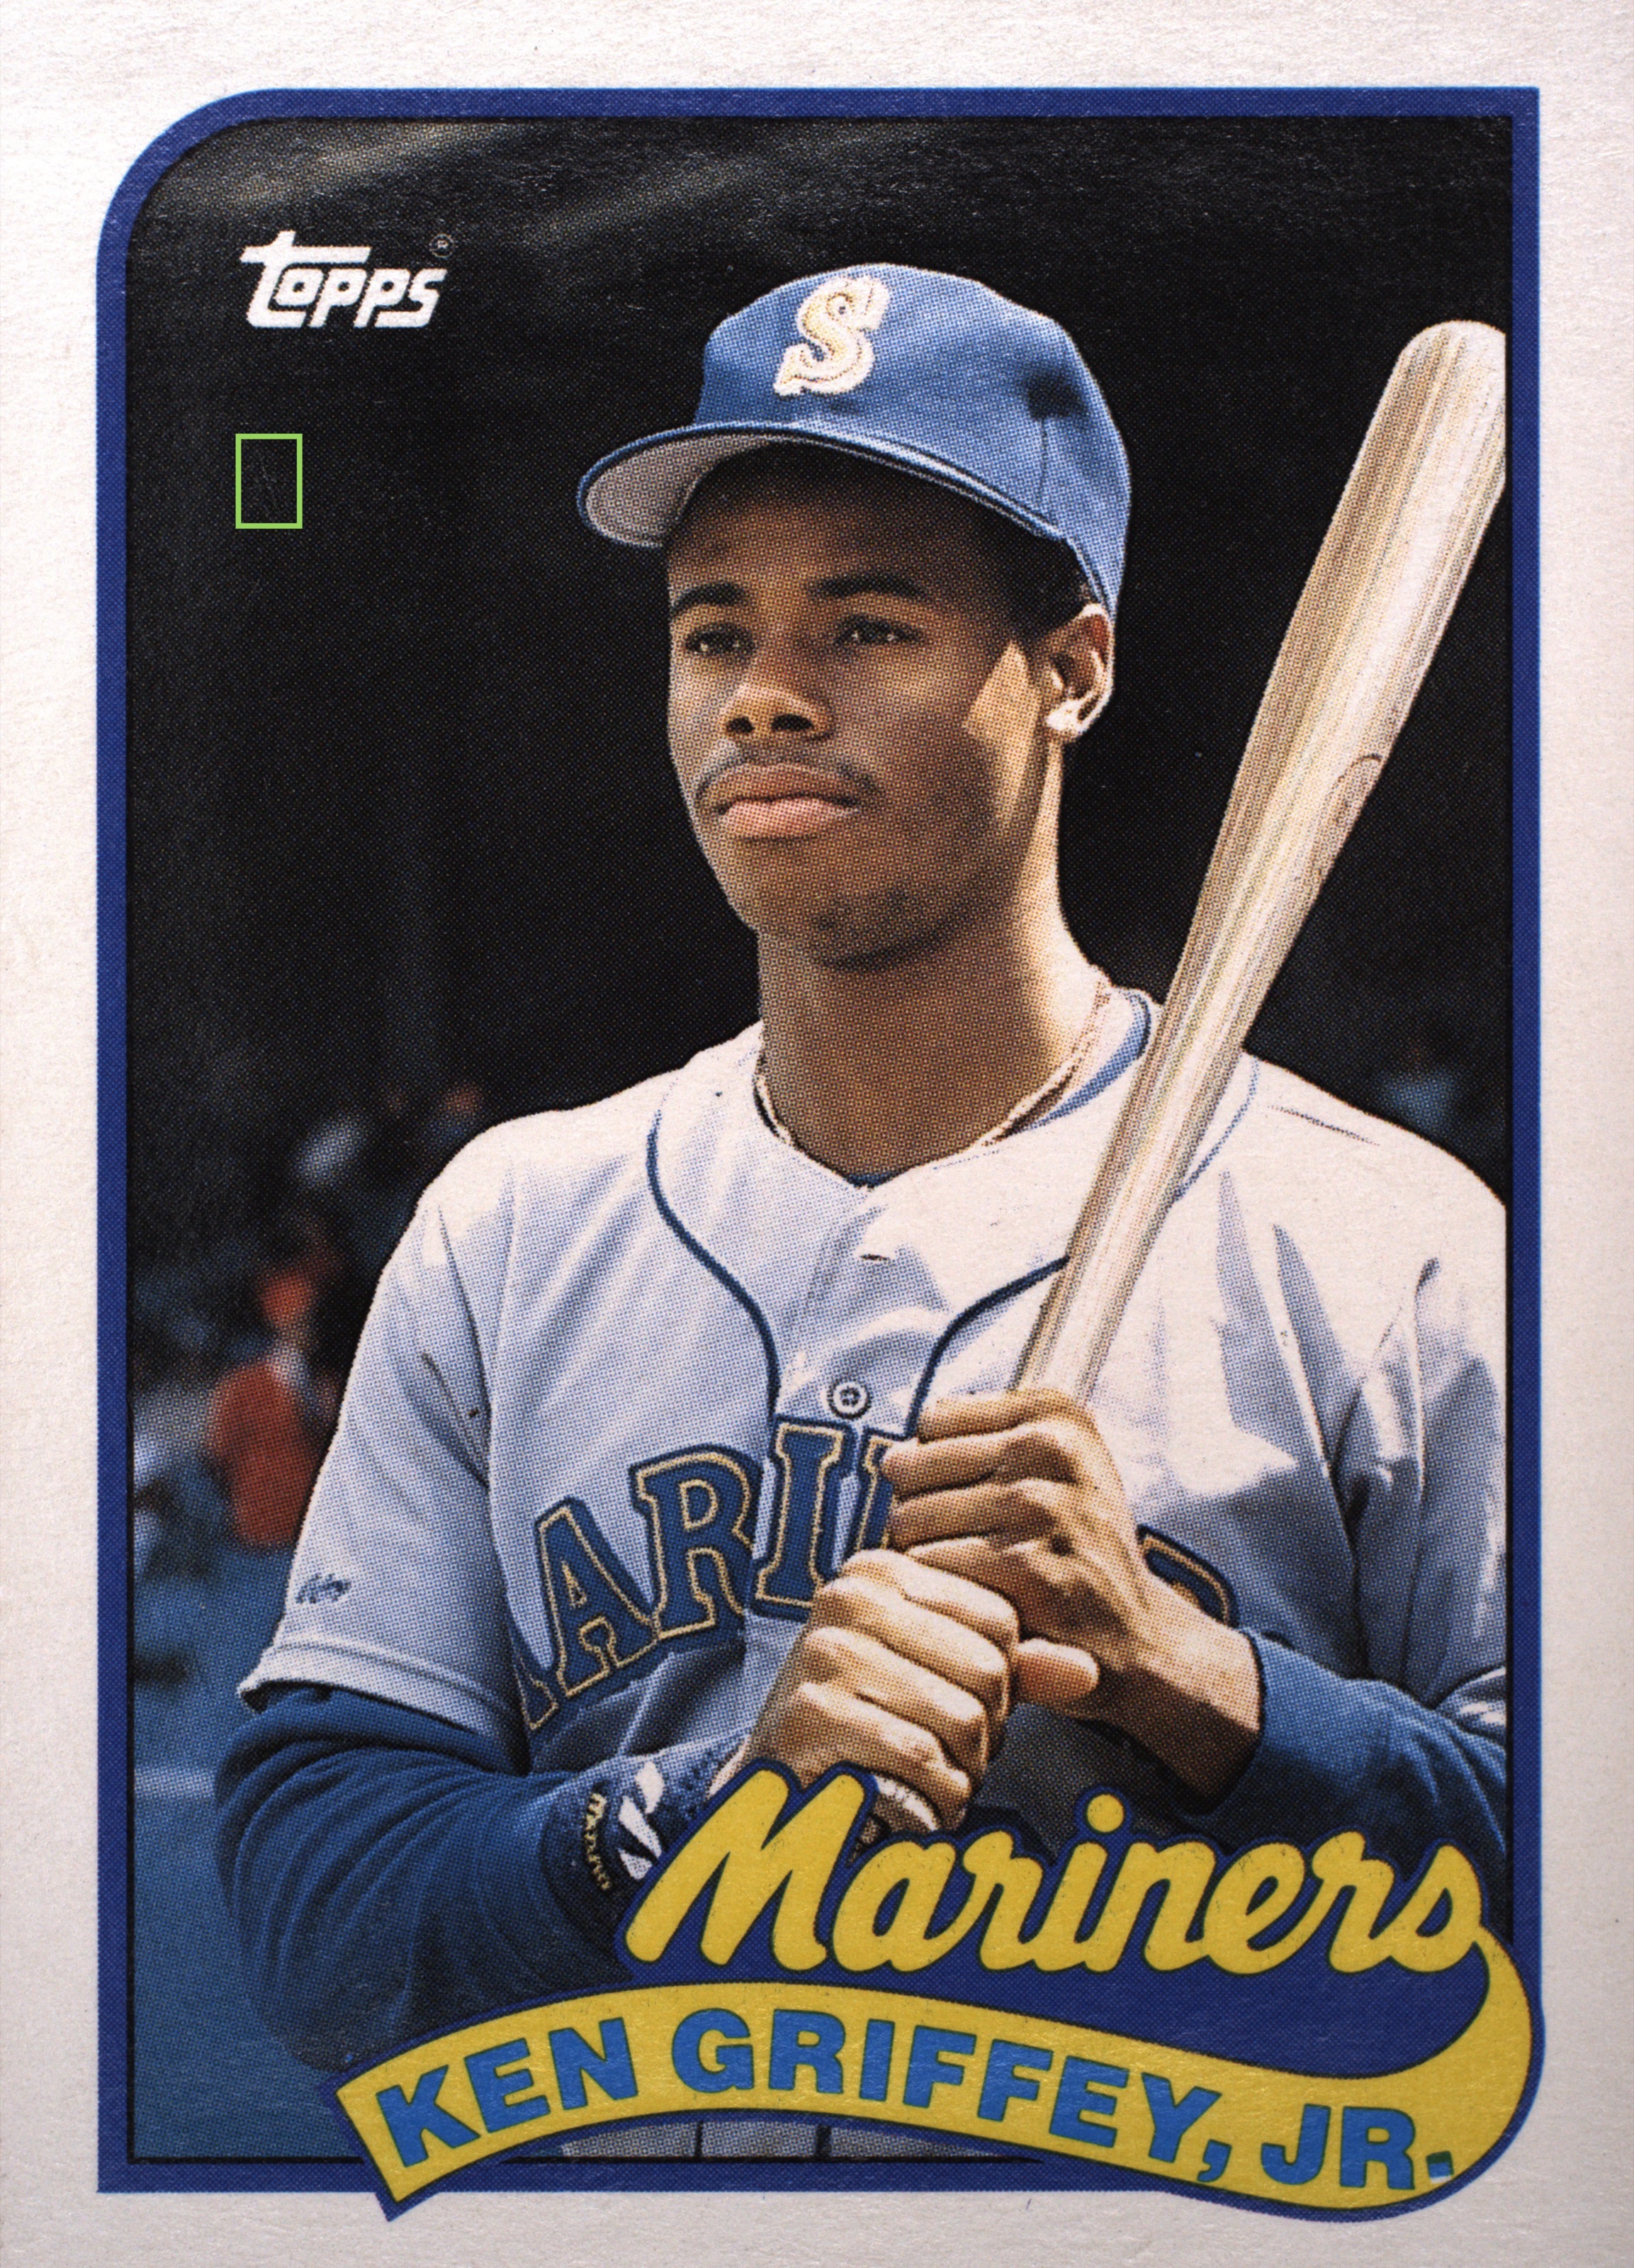
Before cards, this hierarchy screened placental pathology — finding lesions across billions of pixels per slide, where a miss matters more than a grade. Validated in pathology. Validated in art authentication. Now pointed at cards.
Published at the highest level
On a card, the same discipline: every grade traced to something measured, and a system built to know when to doubt itself.
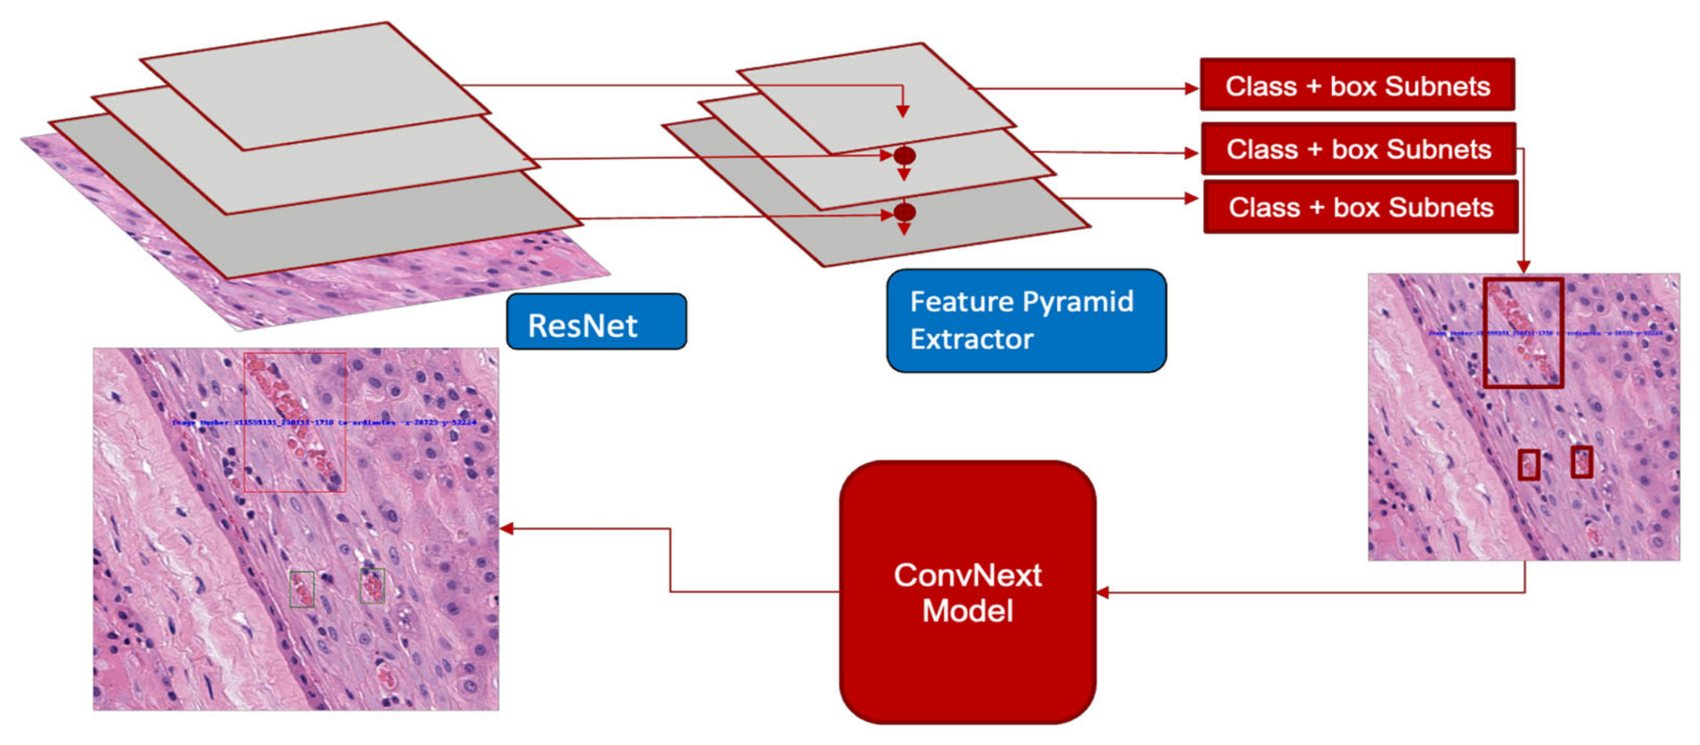
A single placenta holds 3,000–4,000 blood vessels; as few as ten diseased ones put it at high risk of preeclampsia. The hierarchical pipeline detects the vessels, then classifies each one — 99.2% test accuracy.
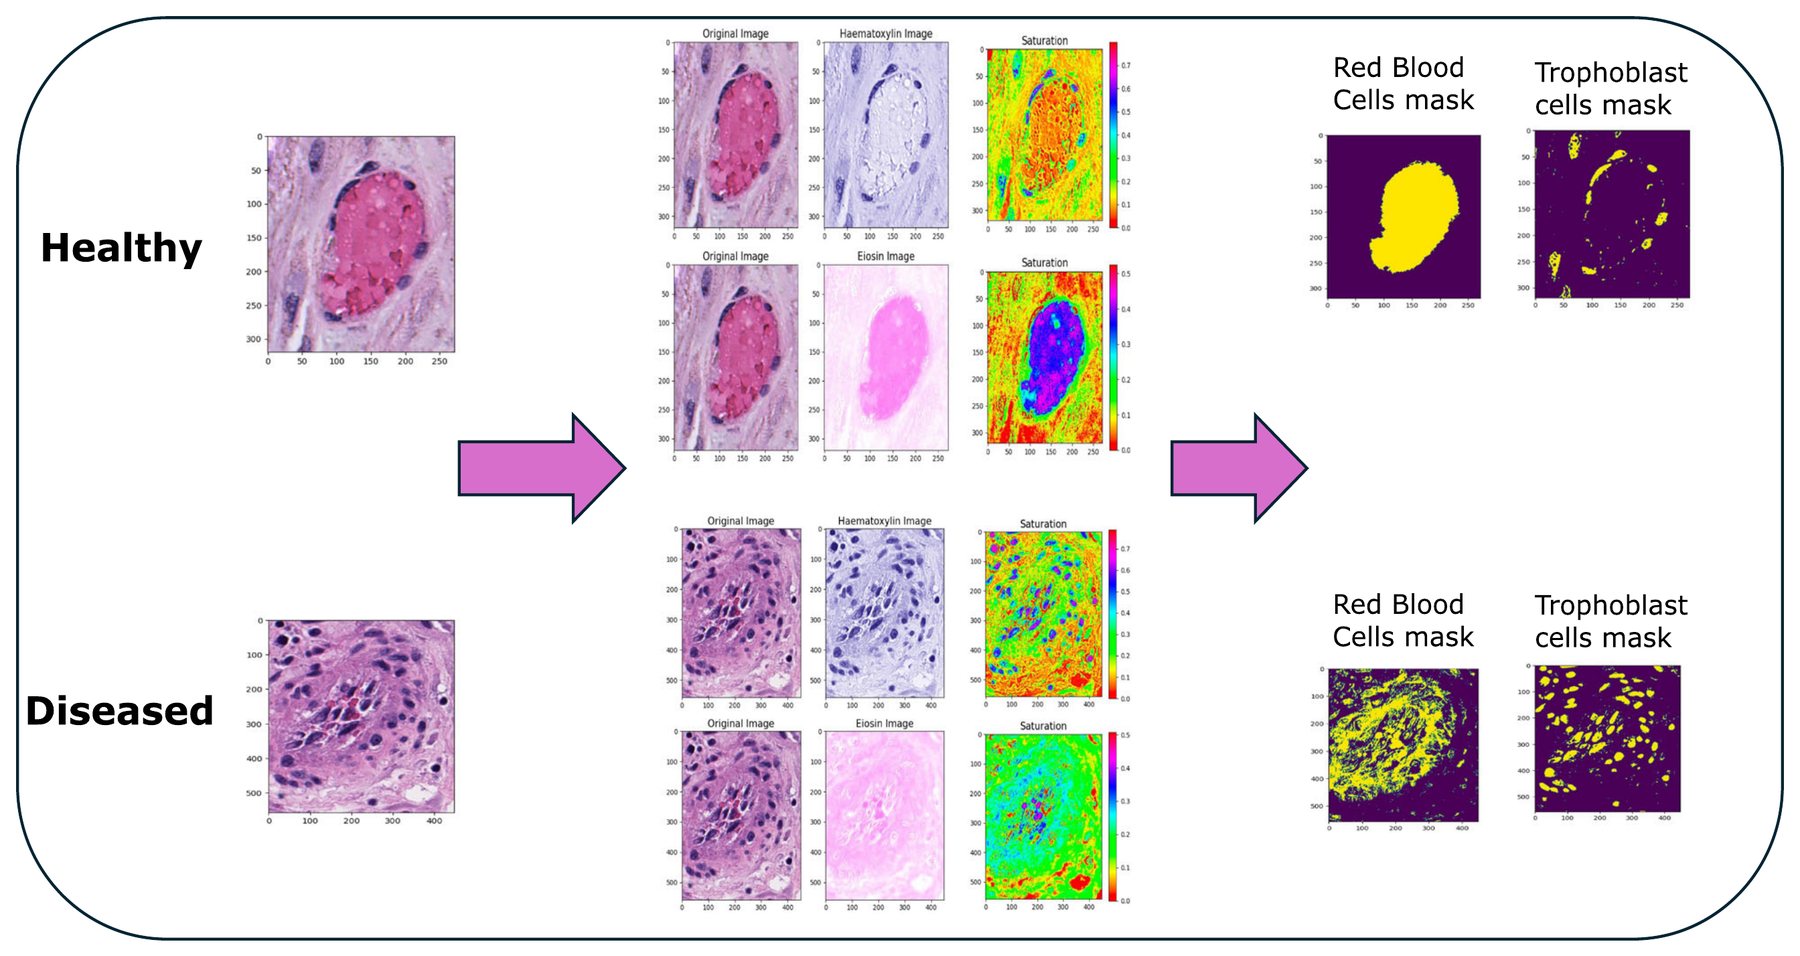
A second, unsupervised layer maps the cells themselves — red blood cells against trophoblasts — and reduces their organization to one measurable score. No cell annotations. No black box.
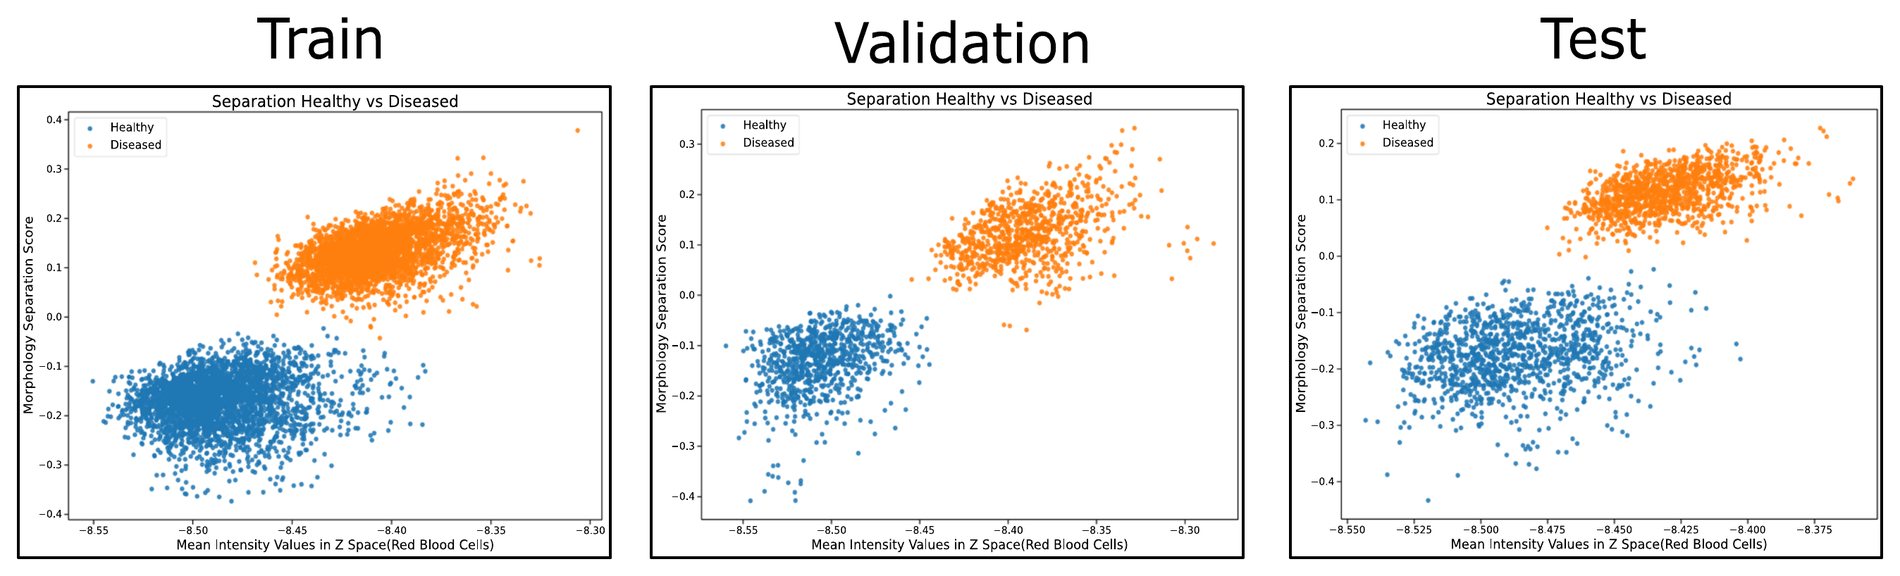
Healthy and diseased vessels separate completely across training, validation and test sets, so the system can flag its own mistakes. Of 12,833 pipeline predictions it flagged 38; in a blind review of the 33 that were vessels, the study’s perinatal pathologist found every diseased vessel correctly identified.
LeDuc, Cagan et al. — npj Digital Medicine (2026). Read the paper →
Published at the highest level
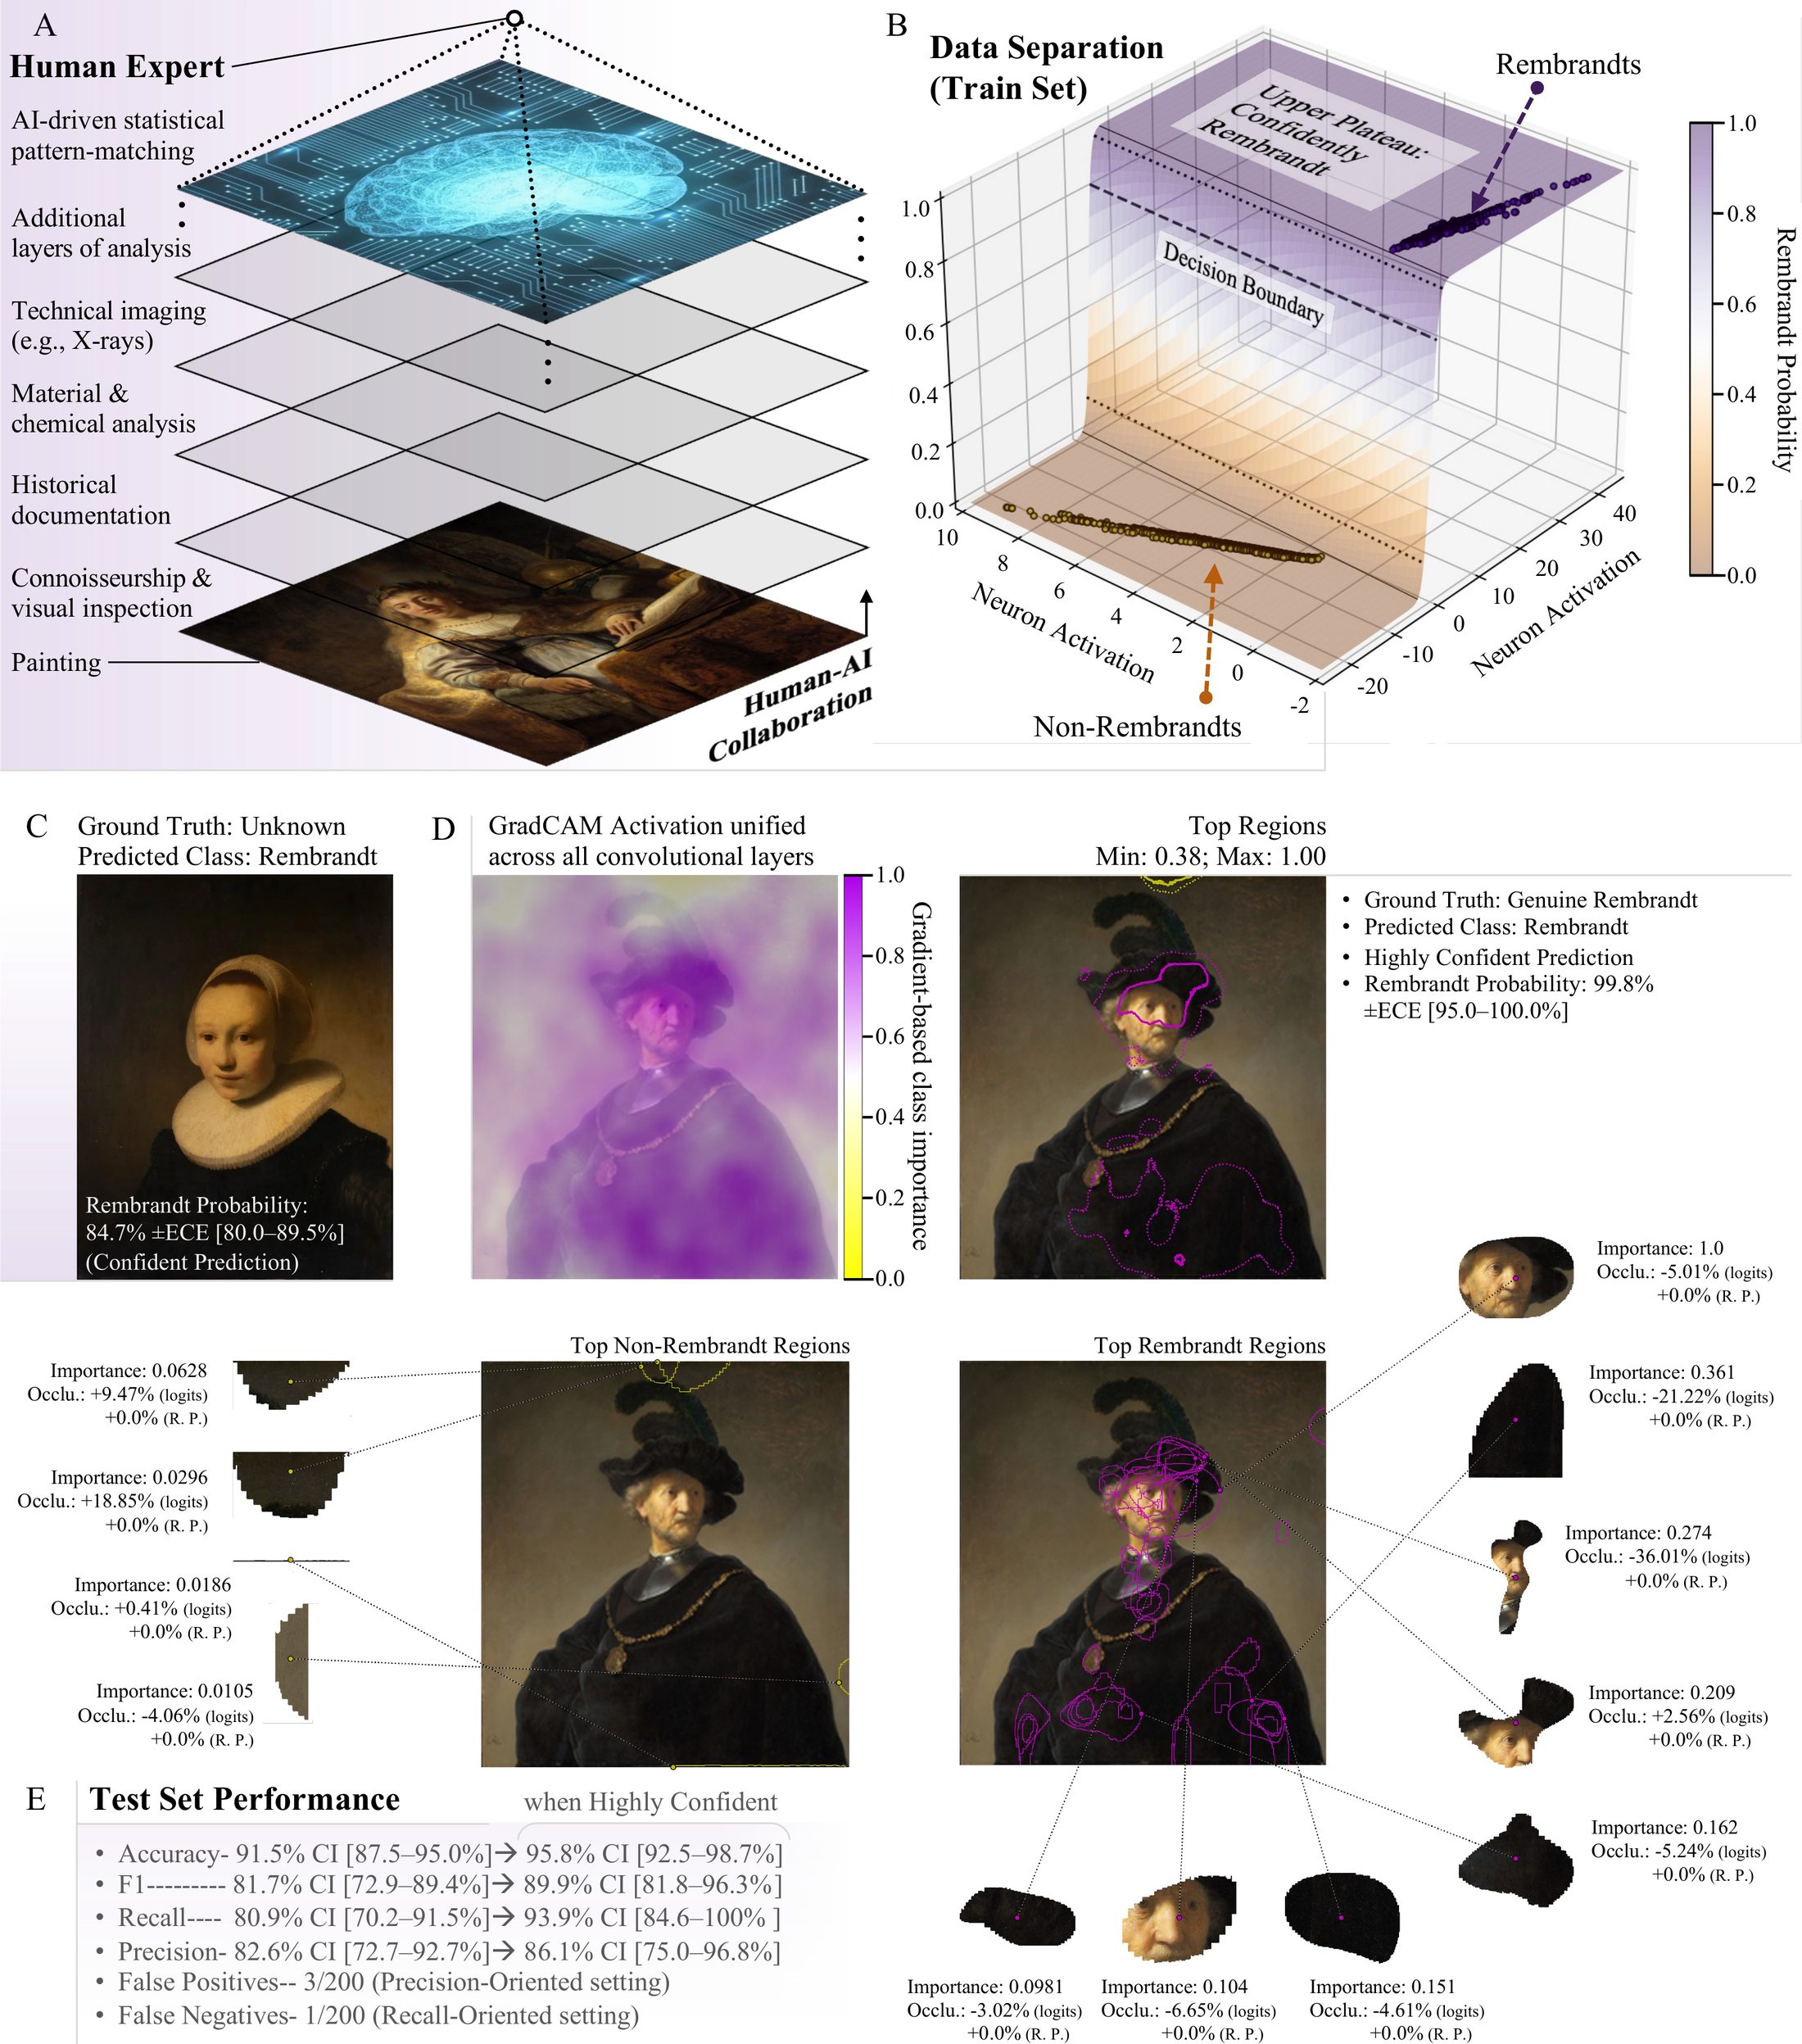
The same model was applied with the same principle — explainable evidence to support a human verdict.
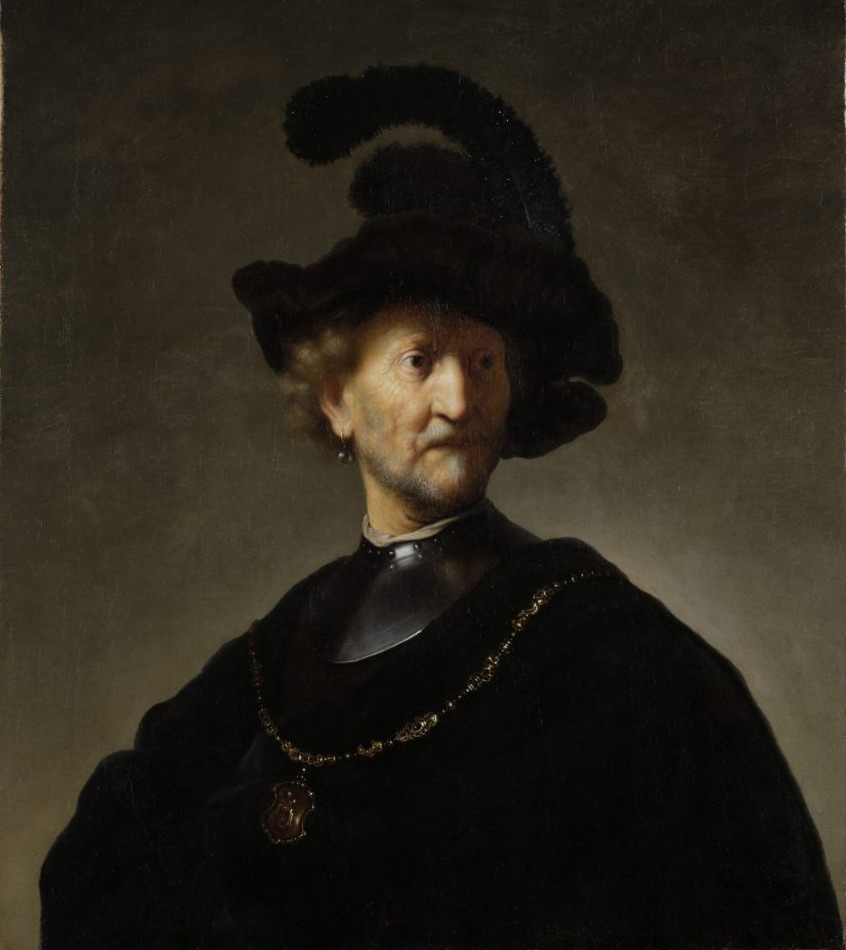
Is it a Rembrandt? Built on 1,325 paintings — the master, his pupils, teachers, peers and influences — the model answers with a calibrated probability, not a bare yes or no.
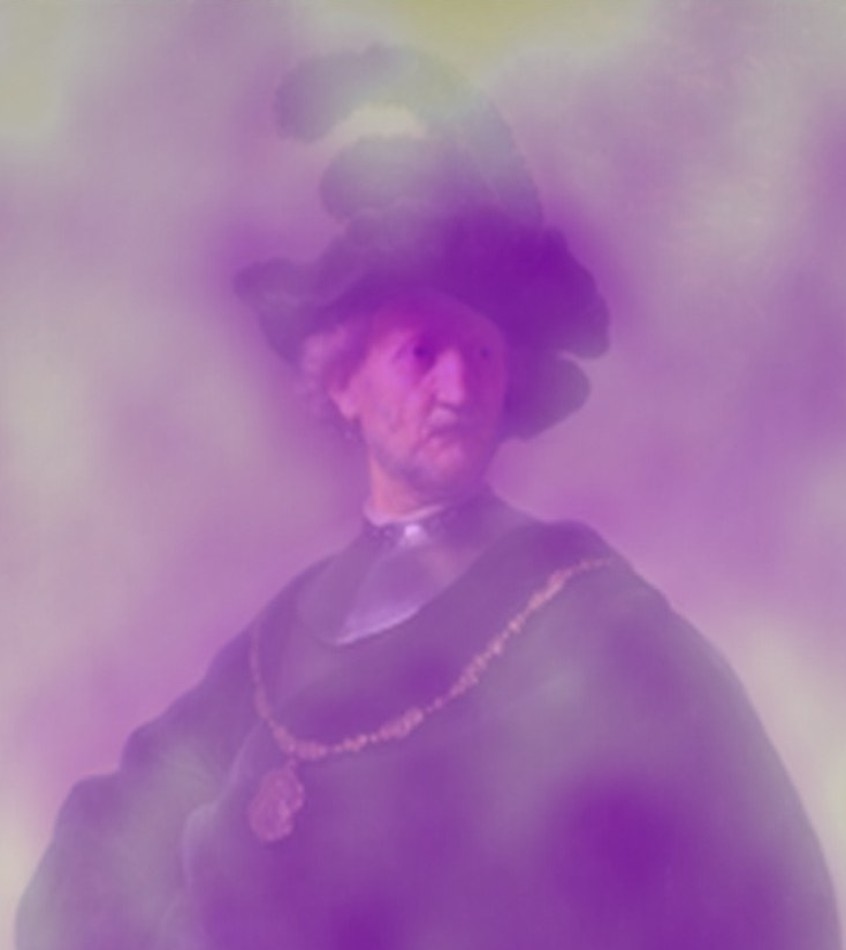
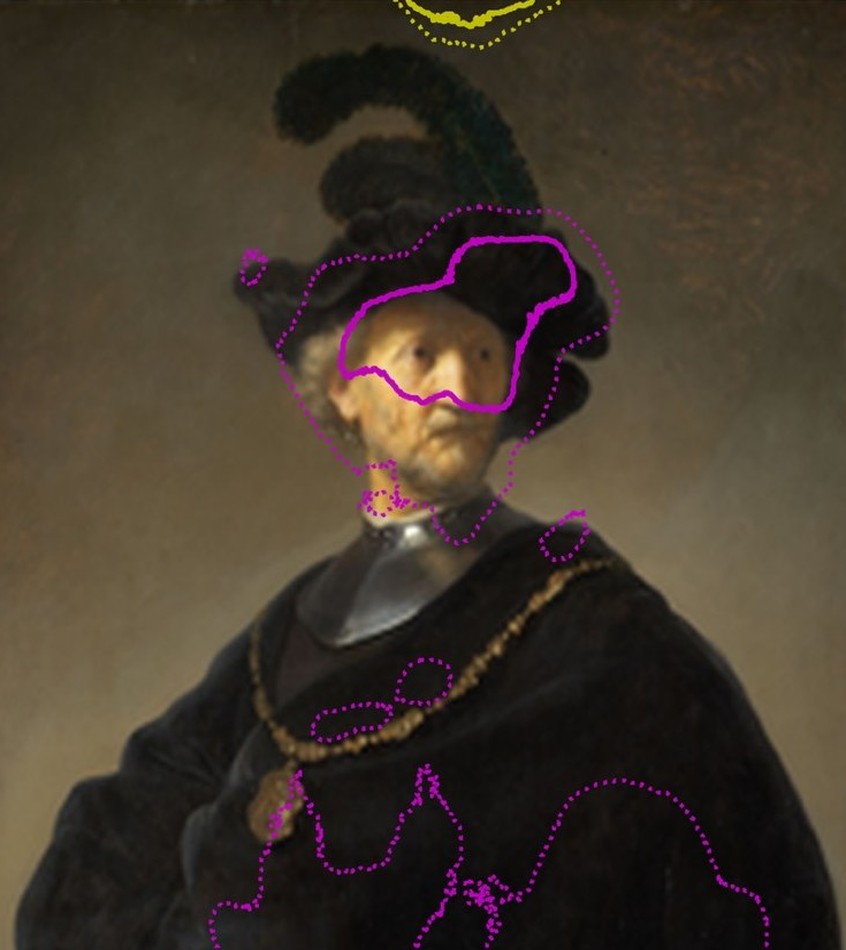
Unified GradCAM combines 17 convolutional layers of the network, from brushstrokes to global light. Purple argues for Rembrandt; yellow against.
Contours mark where the evidence is strongest: the face, especially around the eyes — the part experts say the master usually painted himself. Rembrandt probability 99.8%. Highly confident.
Published at the highest level
Human–AI collaboration
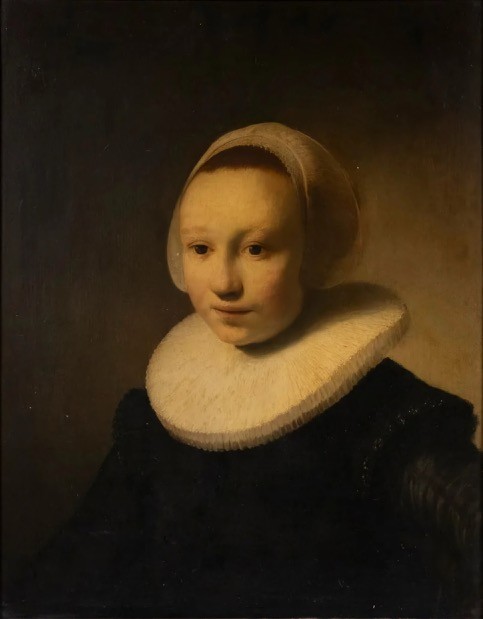
Case · the Maine attic find
Found in an attic in 2024.
Sold for $1.41M.
Still debated.
Tested blind against co-author Arthur K. Wheelock Jr. — over forty years a curator at the National Gallery of Art. On 186 paintings the model matched his attributions 86.6% of the time; where both were highly confident, 93.4%.
For grading: the machine measures, flags and explains. Your graders decide.
Academic technology — who we are
Co-inventor · CMU profile
A University Professor and head of Mechanical Engineering at Carnegie Mellon, Cagan has spent decades advancing computational design and AI-driven engineering. As a co-inventor of the technology behind Cardinal, he brings that expertise to hierarchical learning for card grading — turning visual evidence into consistent, explainable assessments.
Co-inventor · CMU profile
The William J. Brown Professor of Mechanical Engineering at Carnegie Mellon and an AAAS Fellow, LeDuc works at the intersection of engineering and biology. As a co-inventor of the technology behind Cardinal, he brings experience applying these methods to complex biological images to card grading — with annotated evidence that supports a human verdict.
Backed by Control Group — a partner bringing capital and hands-on operating support to take our research from the lab to the market.
Learn about Control Group →